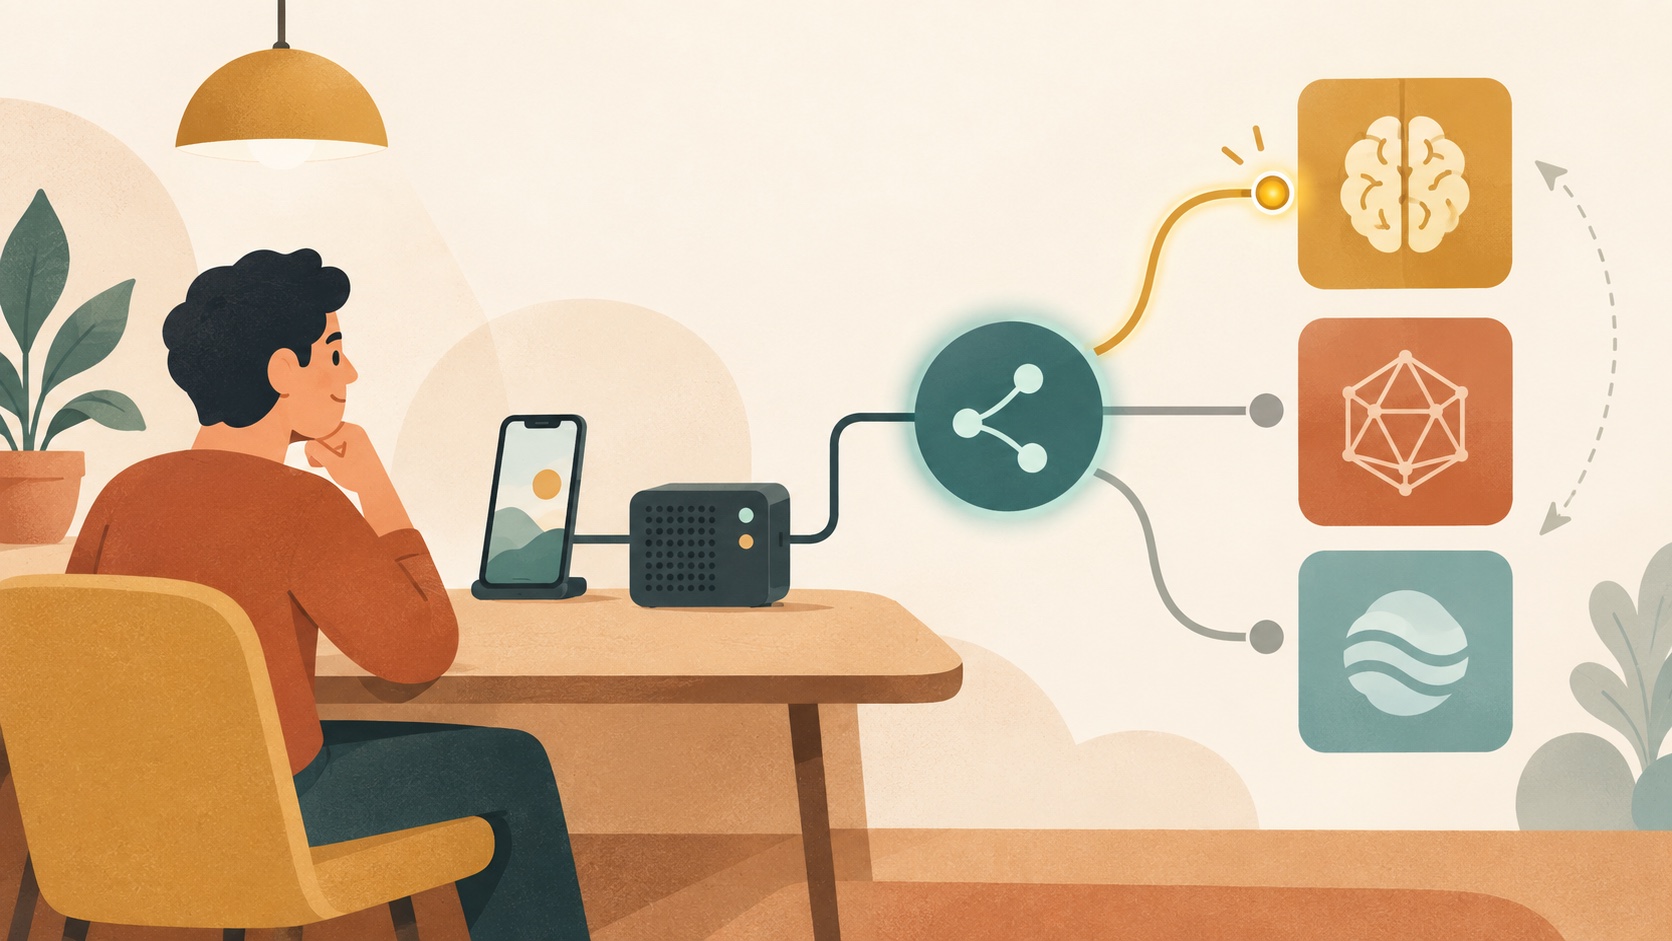
Better and cheaper AI models keep arriving. The model that made sense when you shipped an app may no longer be the best choice a few weeks later. But if that model’s ID lives in a published iOS app or deployed server, each upgrade becomes another release. How can you keep the application current while users run old builds? Haimaker lets you update the models your application uses without redeploying it. Send haimaker/auto as the model ID, then change the default model or prompt-specific rules in the dashboard.
This problem repeats with every model release. Developers need to test quality, cost, and capabilities against their workload. Keeping the model choice outside deployed code lets them act on those results without scheduling another app or server release.
A fixed model ID gets stale after release
A fixed model ID makes every model upgrade depend on the application’s release process. That is manageable while you are building the first version. After launch, each promising model or price change can mean editing code, running tests, deploying servers, or submitting a mobile update. New models can arrive between app releases.
For an iOS app, a model ID embedded in the client cannot change for users who have not installed an update. Apple reviews app updates before distribution, and users may keep older versions long after a new build is available. Moving the API call to your backend avoids putting a provider key in the app, but a model ID hard-coded on that backend still needs a configuration change or deployment.
A gateway endpoint alone does not solve the problem. If a request names a fixed model, the caller remains tied to that choice. OpenRouter, for example, supports named models as well as its own openrouter/auto router. An auto-router can keep the underlying model choice out of deployed code. Haimaker lets you adjust the routing policy for your own prompt classes after the application ships.
How can a deployed app keep up with new models?
Send one stable model ID from the application and keep the selection policy in Haimaker. A router has a default model for unmatched requests and rules that send specific kinds of prompts elsewhere. The router is assigned to an API key. When you change its targets, later requests can reach different models even though the deployed caller keeps sending haimaker/auto.
On a mobile product, the app should call your backend, and the backend should call Haimaker. That keeps the API key off users’ devices. A server application can use the same pattern directly: its request code stays in place while an operator adjusts the router. The setup documentation shows how to create a router, choose a default, assign an API key, and test requests.
import OpenAI from "openai";

// Run this on your backend; do not bundle the API key in a mobile app.
const client = new OpenAI({
  baseURL: "https://api.haimaker.ai/v1",
  apiKey: process.env.HAIMAKER_API_KEY,
});

const response = await client.chat.completions.create({
  model: "haimaker/auto",
  messages: [{ role: "user", content: prompt }],
});
The code above does not need a new model name when the default changes. Haimaker caches router configurations for up to 60 seconds, so allow a minute for a dashboard edit to reach all subsequent requests.
Update the default, then route cheaper work separately
Changing the default model upgrades the broad workload. Rules let you make narrower changes when a new model is cheaper or better for one task. That distinction matters: an app might need a capable default for long-form editing while sending short title suggestions to a lower-cost model. Both decisions can change after release without altering the caller’s model ID.
Imagine a writing app whose backend sends every AI request through the same router. A newly released model improves its long-form edits, so the team tests it and changes the router’s default. Later, a cheaper model handles title suggestions well enough. The team adds a rule with examples such as “Suggest five short titles for this note” and “Give this draft a concise heading,” then points that rule at the cheaper model. Users on older app versions receive both changes through the existing backend.
For example-based rules, use 3 to 10 representative prompts per task. A match routes the request to the rule’s target; unmatched requests use the default. Capability checks prevent a rule from sending a vision, tool-use, or structured-output request to a model that cannot handle it. The routing logs show the resolved model and the rule that selected it. For the mechanics behind matching and fallback, see our routing walkthrough and cost-routing guide.
What does this change for a team after launch?
The main benefit is that model selection can follow the workload instead of the release calendar. A team can adopt a new default, move a repetitive prompt class to a cheaper model, or restore an earlier target if results get worse. Server code and installed mobile clients continue to make the same API request. The work shifts to testing and reviewing the routing decision.
| Change after launch | With a fixed model in code | With haimaker/auto |
|---|---|---|
| A better general model arrives | Change the model ID and release code or config | Test it, then change the router’s default |
| A cheaper model fits one prompt class | Add application routing logic and deploy it | Add or edit a rule for that prompt class |
| A model change hurts output quality | Revert the code or config change | Restore the earlier router target |
| Users still run an older mobile build | The embedded model ID remains old | The backend can use the current router policy |
This also helps when server releases have unrelated work pending. A model decision does not have to wait for that deployment window. Separate workloads can use separate routers by assigning them to different API keys; Haimaker supports one router per key.
Routing changes still need the same judgment as code changes. The dashboard sandbox shows which model a prompt would select, but it does not prove the answer is good. Run representative prompts against the proposed model, inspect real output, watch the resolved-model logs, and return to the previous target if quality slips. Haimaker changes model selection; changing prompts, tool schemas, or application behavior still requires application work.
Keep model choice ready for the next release
Create a router, choose a default model, and assign it to the API key your backend uses. Send haimaker/auto in the request, then test a few prompts that represent the workload. When a new model arrives, evaluate it against those prompts before changing the default or a narrow rule. The Haimaker documentation covers the router setup, test sandbox, and routing history.
New models can arrive before your next app release. Keeping the model choice in Haimaker lets the application stay current while developers spend their release cycles on changes that require new code.
Frequently asked questions
How can I change the AI model in a published mobile app?
Have the app call your backend, and have the backend send model: ‘haimaker/auto’ to Haimaker. You can then change the router’s default model or prompt rules in the dashboard without submitting a new mobile build. Router changes can take up to 60 seconds to take effect.
Does switching models through Haimaker require a server deployment?
No. If the deployed server already sends model: ‘haimaker/auto’ with an API key assigned to a router, you can change the router’s model targets in the dashboard. Changes to application prompts, request formats, or code still require the usual deployment.
Can I move only simple prompts to a cheaper model?
Yes. Add a rule with 3 to 10 example prompts for a simple task and select a cheaper target model. Haimaker checks that the target supports the request, while prompts that do not match a rule use the router’s default model.